Blog
Notes from turning ideas into live, running products — AI products, cloud storage, SEO and full-stack practice. The brief is short and frequent; this is long and occasional.
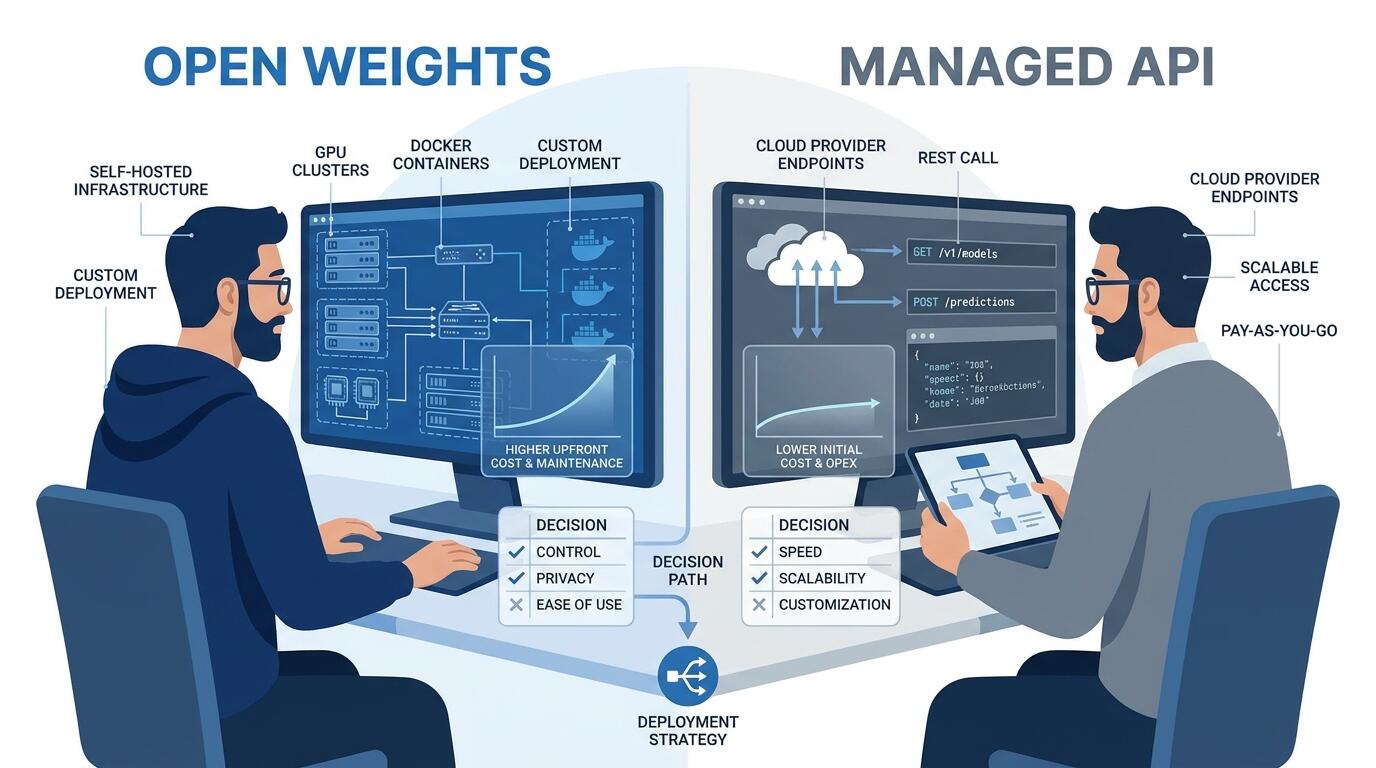
- 2026-10-29 Model Strategy 101: Choosing Between Open Weights and API This Quarter This article provides a structured decision framework for AI engineering teams choosing between open-weights self-hosting and managed API access. Targeting builders in production stages, it covers cost modeling, compliance auditing, operational capacity, and hybrid architectures. Key takeaway: the choice is a cost-structure and ops decision, not purely a capability one. Read →
- 2026-10-29 Why Retrieval Quality Degrades in Production (and How to Catch It Early) A practitioner's guide for engineers managing production RAG systems, covering why retrieval quality silently degrades and how to detect it early. Core argument: proactive monitoring via baselines, canary loops, and spot checks beats reactive fixes. Key takeaways: four distinct root causes (corpus staleness, query shift, embedding drift, contamination) each require unique remediation, and instrumentation from day one is essential. Read →
- 2026-10-29 A Technical Founder's Guide to Evaluating RAG Vendors This Quarter A comprehensive technical guide for founders and lead engineers on evaluating RAG vendors, covering retrieval quality benchmarking, chunking control, latency stress-testing, observability, lock-in risk, and contract review. Core argument: RAG vendor selection is an architectural decision, not procurement. Key takeaway: benchmark on your own data, demand chunk-level observability, and scrutinize data portability before signing. Read →
- 2026-10-28 Why Agent Autonomy Is the Wrong Question for Most Teams This Quarter This article argues that AI teams are prematurely debating agent autonomy before solving foundational prerequisites: observability, output contracts, and failure recovery. Targeting AI engineers and product leads, it advocates for per-step trust calibration and reliability-first sequencing. Key takeaway: autonomy is an output of reliable systems, not a design input — nail observability this quarter first. Read →
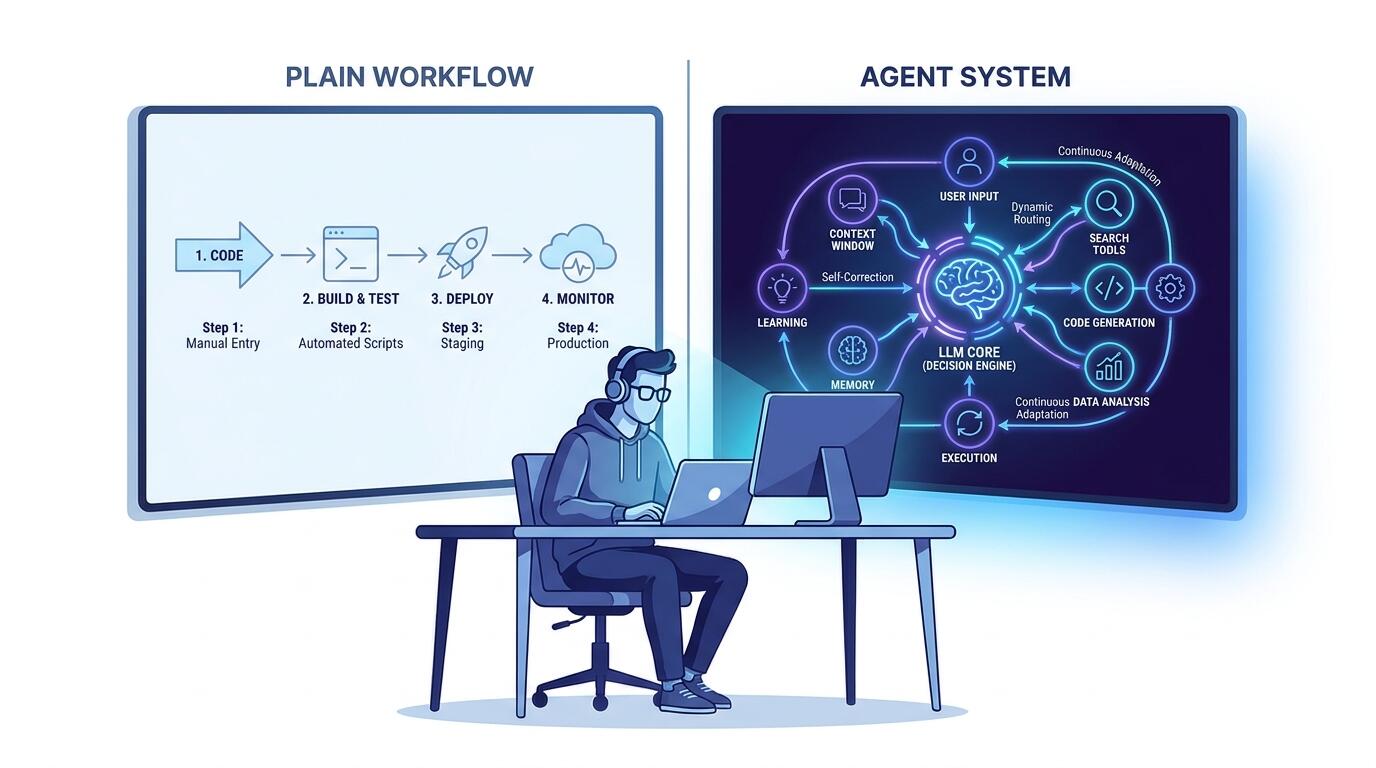
- 2026-10-28 Comparison: Plain Workflows vs Full Agent Systems for Solo Builders This article guides solo builders in choosing between plain AI workflows and full agent systems, arguing that deterministic pipelines should be the default for most use cases. It evaluates both architectures across implementation speed, debuggability, cost, and maintenance — concluding that agent systems only justify their overhead when task structure is genuinely open-ended. Read →
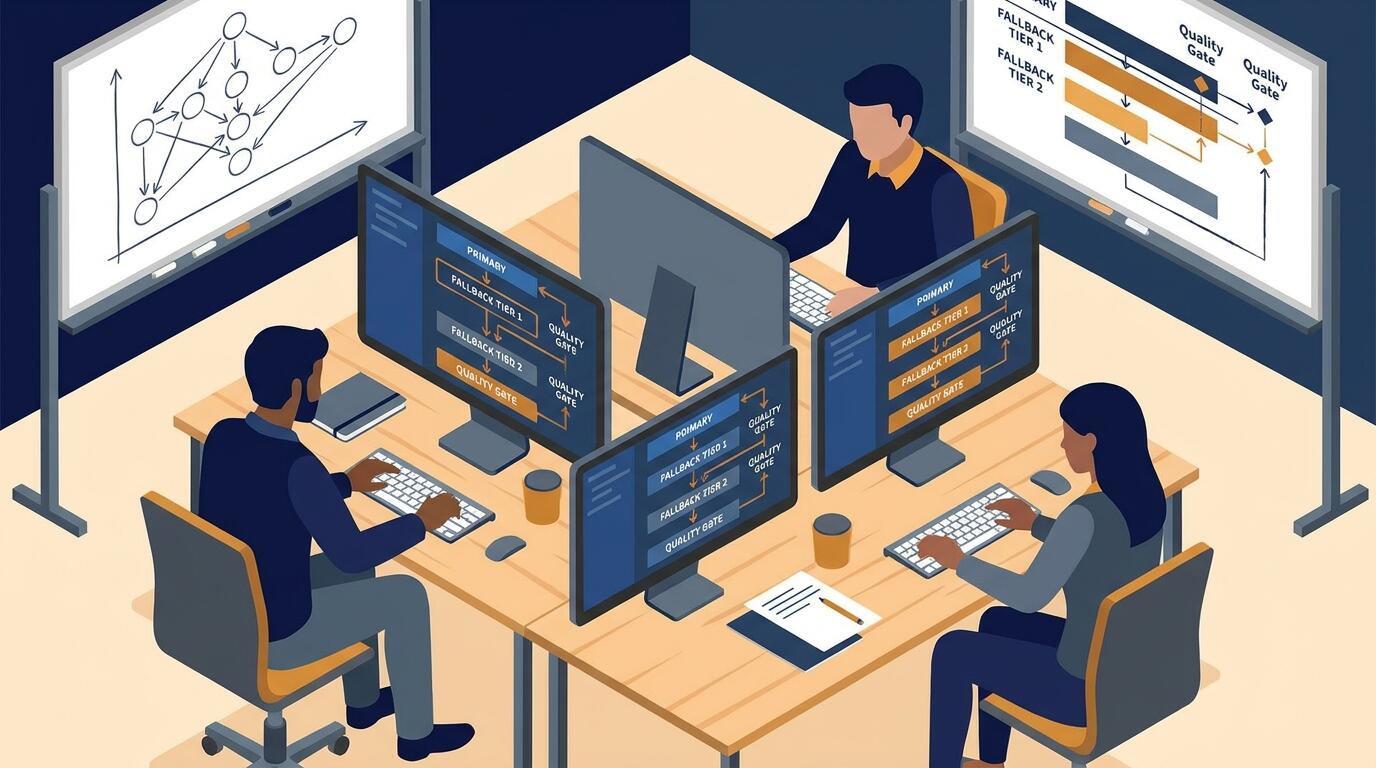
- 2026-10-28 A Small Team's Guide to Fallback Design in Agent Systems A practical engineering guide on fallback design for AI agent systems, targeting small teams (1–5 engineers). It covers failure taxonomy, tiered fallback strategies, quality gates, escalation paths, replay capability, and instrumentation. Key takeaway: classify failures before coding, define tiered alternatives for every dependency, and instrument from day one to drive iterative reliability improvements. Read →
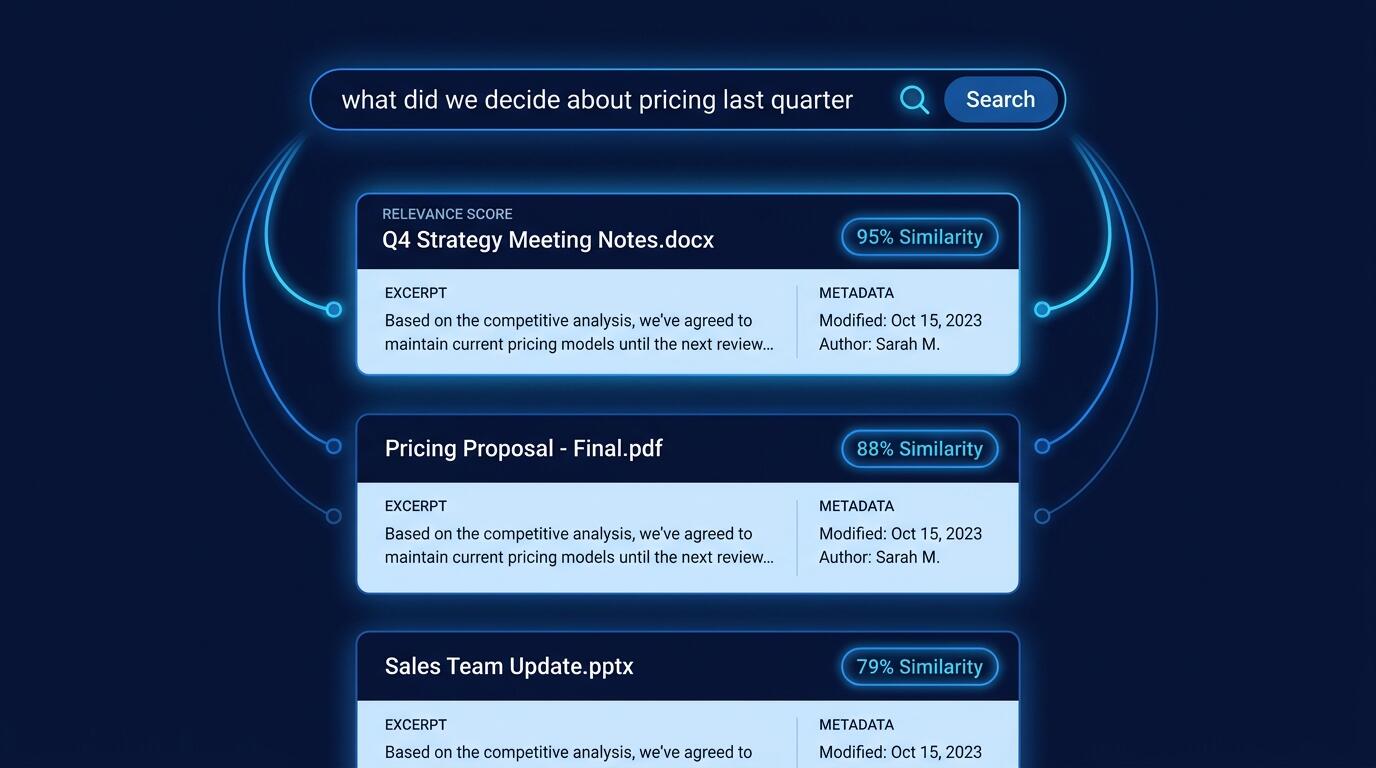
- 2026-10-27 aipan for Beginners: What Semantic File Search Actually Looks Like This article explains semantic file search — how it differs from keyword search, how it works via vector embeddings, and how to use aipan for local document retrieval. Targeting engineers, PMs, and technical leads, it covers practical setup, result interpretation, chunking, and staleness. Key takeaway: semantic retrieval matches meaning, not tokens, and compounds in value as file libraries grow. Read →
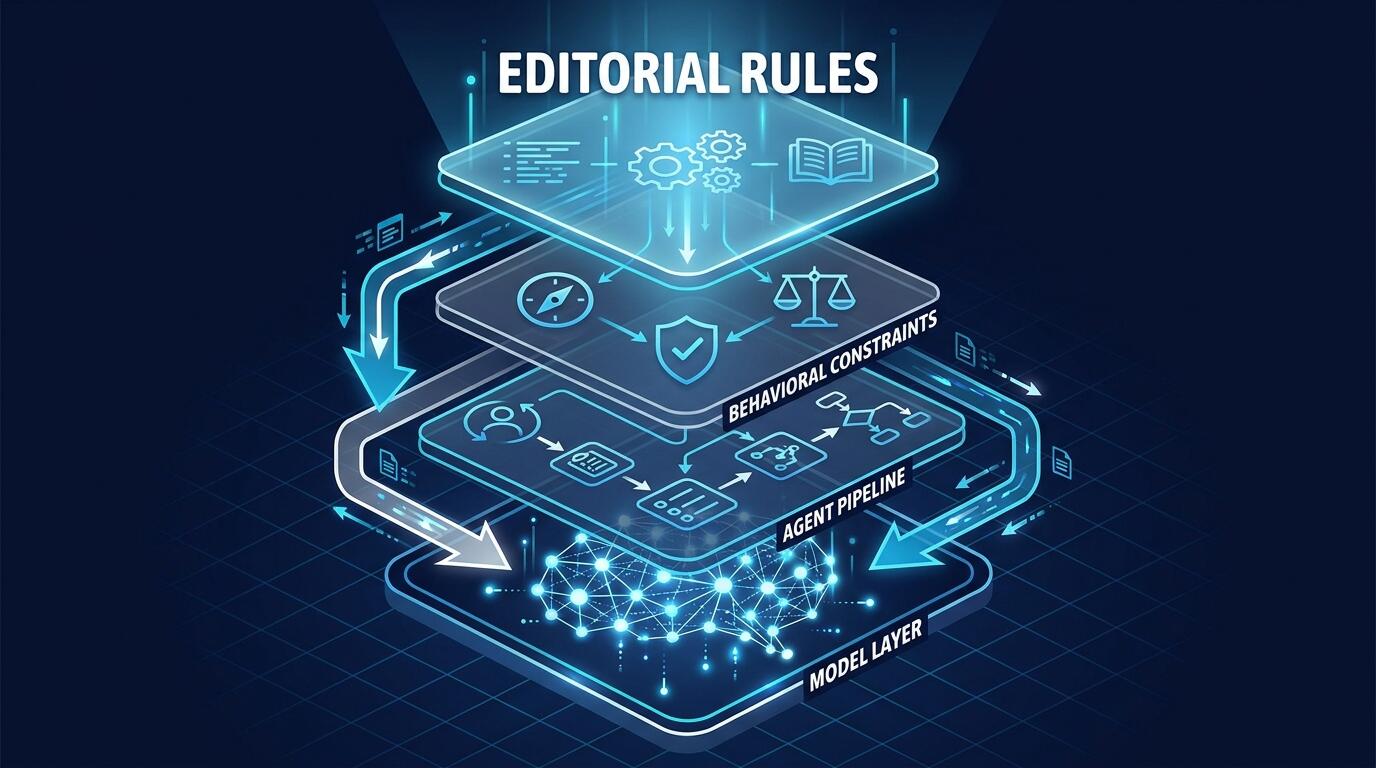
- 2026-10-27 Why Editorial Rules for Agents Matter More Than the Model You Choose This article argues that editorial rules governing AI agent behavior matter more than model selection for production systems once a basic capability threshold is met. Targeting engineering teams and AI product builders, it explains behavioral drift, verification at scale, and trust as engineering properties. Key takeaway: write a versioned behavioral specification before benchmarking models. Read →
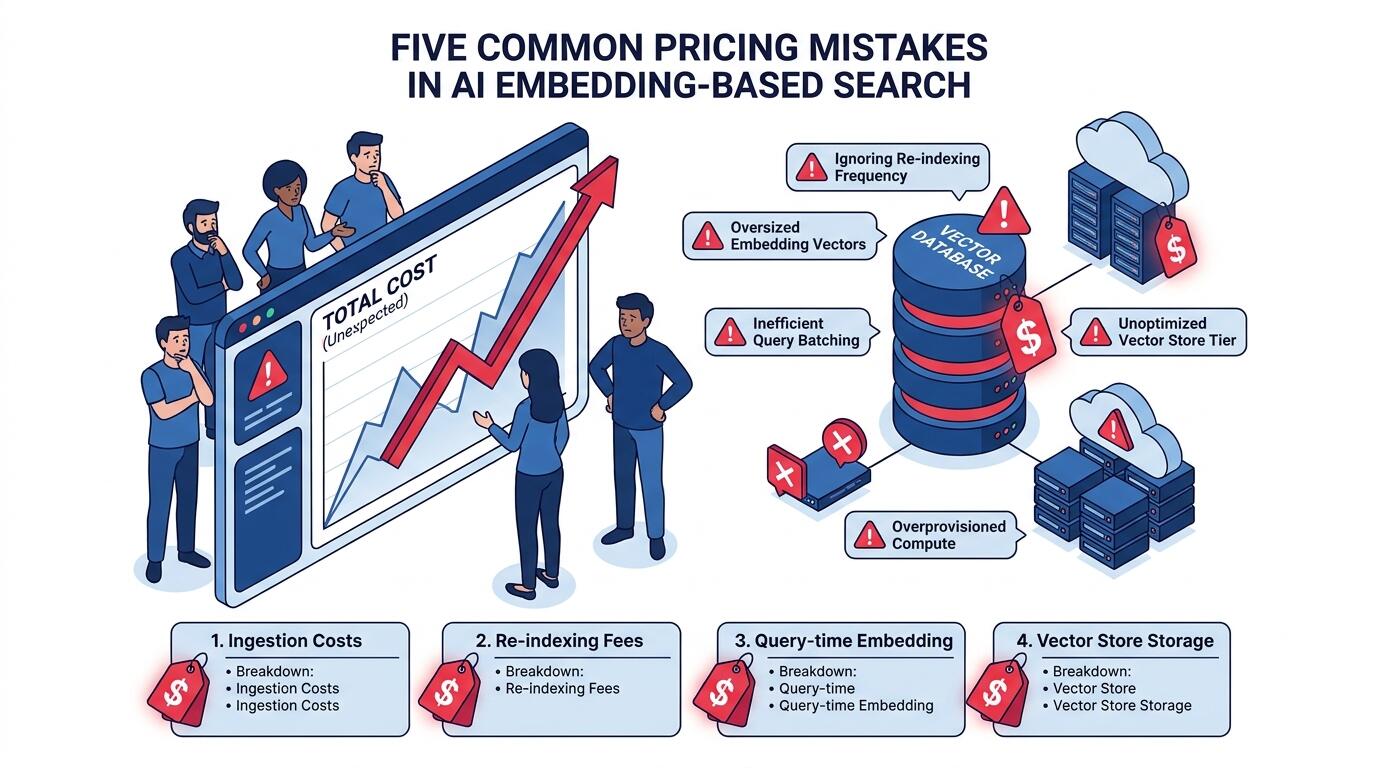
- 2026-10-27 Five Mistakes to Avoid When Pricing Embedding-Based Search Features This article identifies five critical pricing mistakes teams make when building embedding-based search features in AI products — from mismodeling embedding costs to ignoring vector store expenses and skewed usage distributions. Targeting AI product builders and engineering leads, it delivers actionable cost-modeling frameworks and scenario-based recommendations to prevent margin erosion at scale. Read →
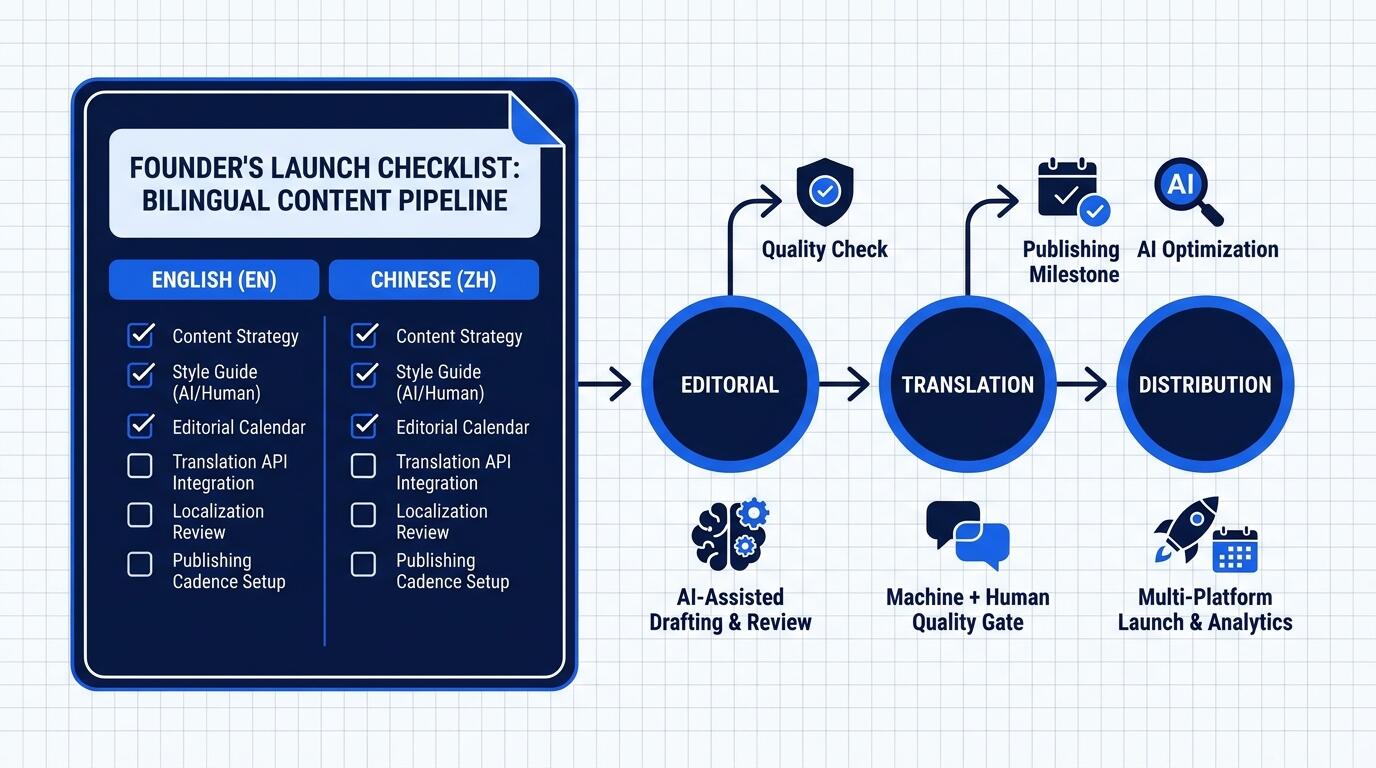
- 2026-10-27 A Founder's Checklist for Launching a Bilingual Content Pipeline A practitioner-built 9-step checklist for AI product founders launching a bilingual content pipeline. Covers canonical language definition, language-agnostic editorial rules, workflow mapping, tooling, quality verification, distribution, cadence, metrics, and documentation. Key message: structural decisions outweigh linguistic ones in pipeline success. Read →
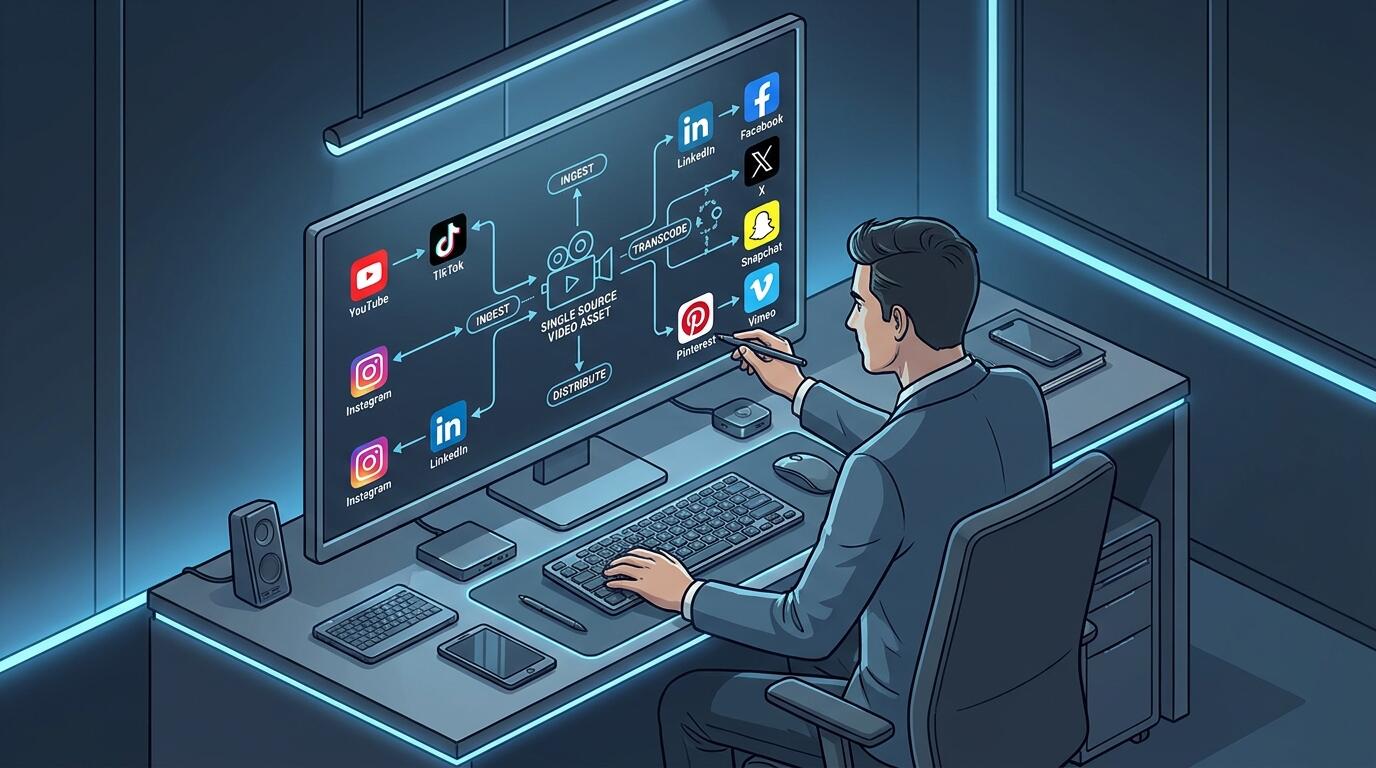
- 2026-10-27 Deep Dive Into Nine-Platform Video Distribution From One Source Issue This article tackles the engineering challenges of distributing a single video source across nine platforms (YouTube, TikTok, LinkedIn, etc.), identifying five core failure layers: codec incompatibility, aspect ratio mismatch, metadata divergence, caption fragmentation, and API rate limits. Targeting content engineers and AI pipeline builders, it advocates defining a canonical source spec and adapter-pattern architecture as the most scalable, maintainable solution. Read →
- 2026-10-27 Advanced Tactics for Reducing Storage and Embedding Costs Together This practitioner guide argues that AI embedding generation and vector storage costs must be optimized jointly, not in isolation. Targeting ML engineers and AI infrastructure architects, it covers MRL dimensionality reduction, scalar/binary quantization, tiered storage, and embedding caching as compounding cost levers. Key takeaway: profile cost drivers first, then apply combined tactics for maximum savings without sacrificing retrieval quality. Read →
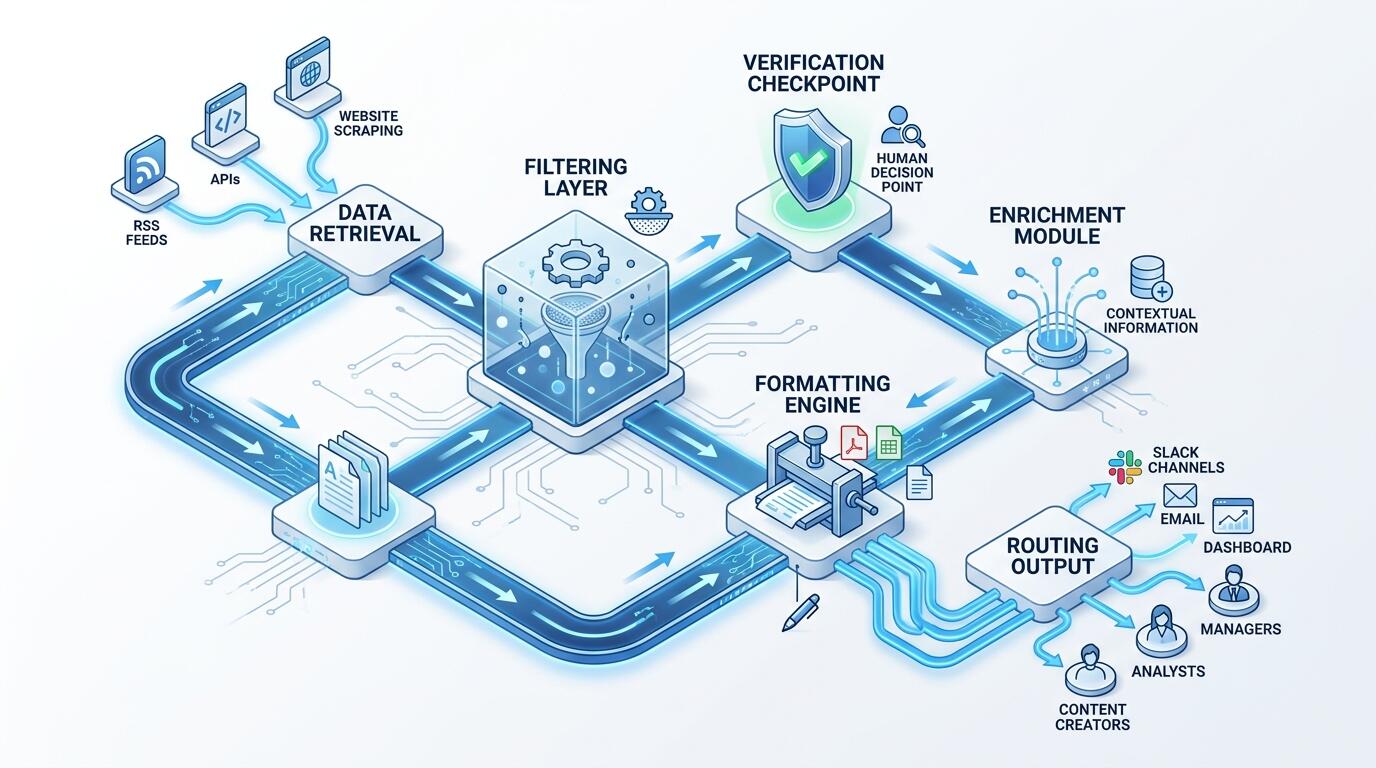
- 2026-10-25 The Agent Pipeline for Marketers: What a Daily AI Briefing Can Teach Your Team This article argues that a daily AI briefing system is a working reference architecture for marketing teams building agent pipelines, covering retrieval, filtering, verification, formatting, and routing stages. Targeting marketing/growth teams and technical leads, it provides a 3-step quick-start, a platform comparison table, failure-mode analysis, and an FAQ. Key takeaway: use a curated briefing to calibrate pipeline quality before building internally. Read →
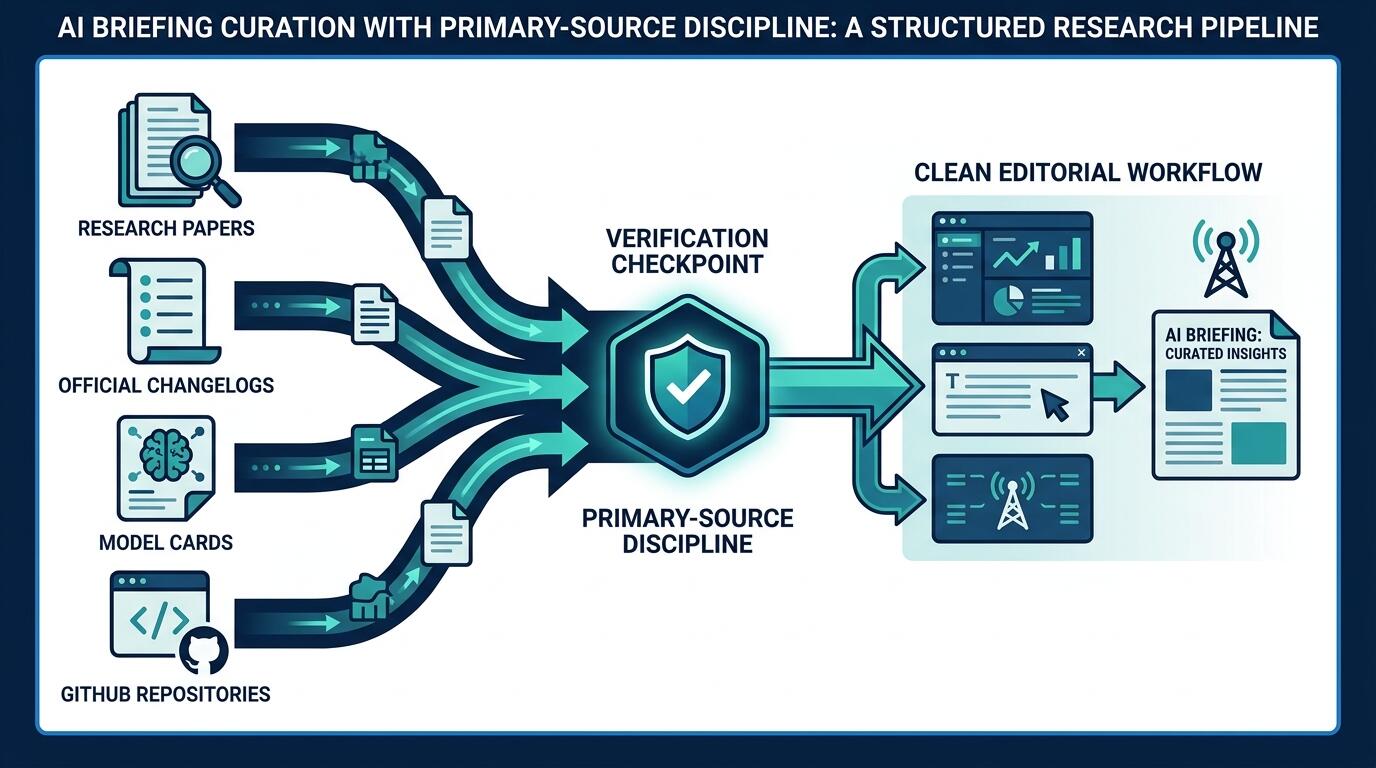
- 2026-10-25 Case Study: How Primary-Source Discipline Shaped This Quarter's Briefing This article compares primary-source discipline vs. aggregated reporting for AI briefing curation, targeting AI product builders and developers. It argues that fewer, fully-sourced briefing items outperform high-volume aggregated digests for actionable decision-making. Key takeaway: fidelity and traceability beat coverage breadth for builders making real product decisions. Read →
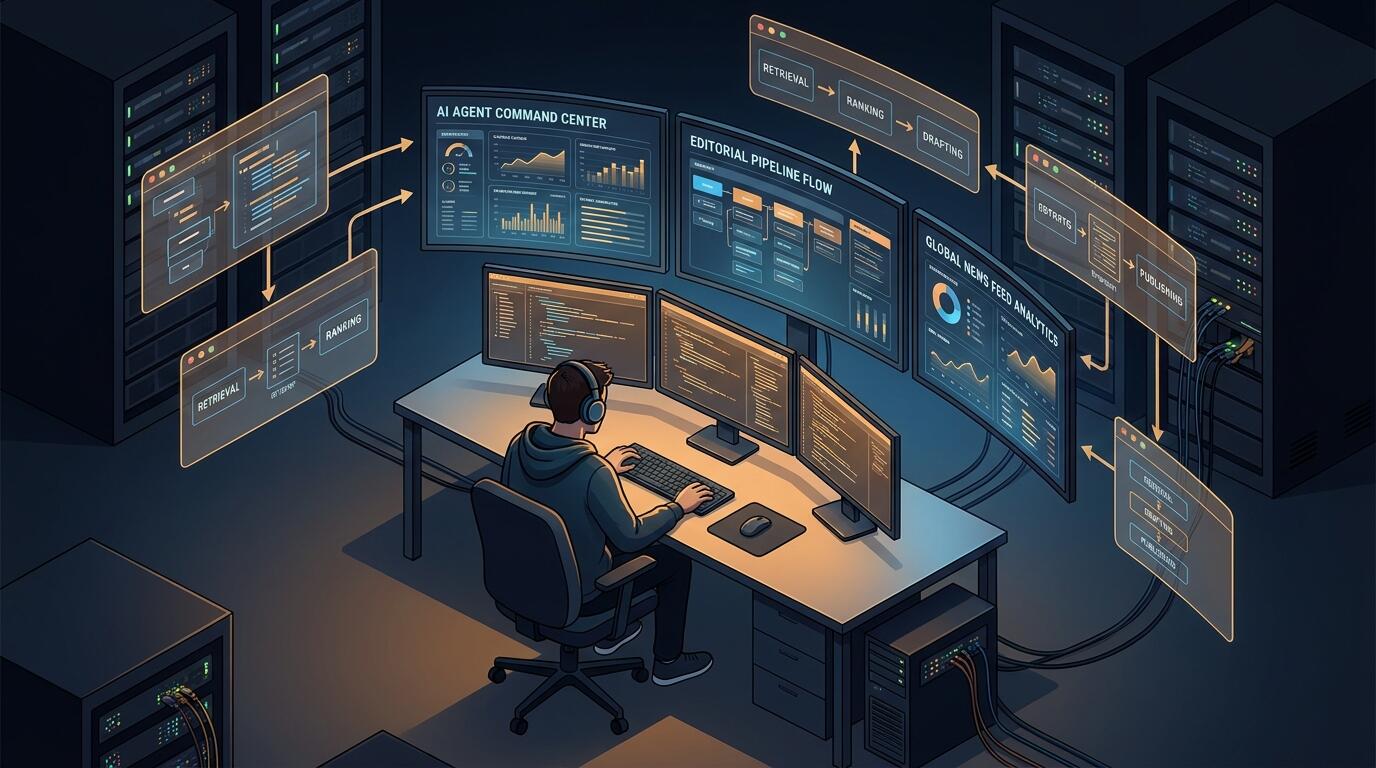
- 2026-10-25 Interview: What It's Like Running an Automated Newsroom Solo A practitioner guide for solo engineers building automated AI newsrooms, covering pipeline stages (retrieval, ranking, drafting, publishing), failure modes, and editorial governance. Key argument: competitive advantage comes from editorial rule quality and source governance, not pipeline sophistication. Audience: technical builders and independent developers entering AI-powered publishing. Read →
No posts yet