NVIDIA serves the 753B-parameter GLM-5.3 across two DGX Stations, peaking at 607.8 output tokens per second at concurrency 16
Frontier-scale open models no longer fit on one machine. How two workstations become one inference endpoint, and the measured numbers under load.
// Key points
- GLM-5.3 NVFP4 is a quantized version of Z.ai's MoE model: 753 billion parameters with 40 billion active per token, about 464 GB, more than the 252 GB of HBM3e on one GB300.
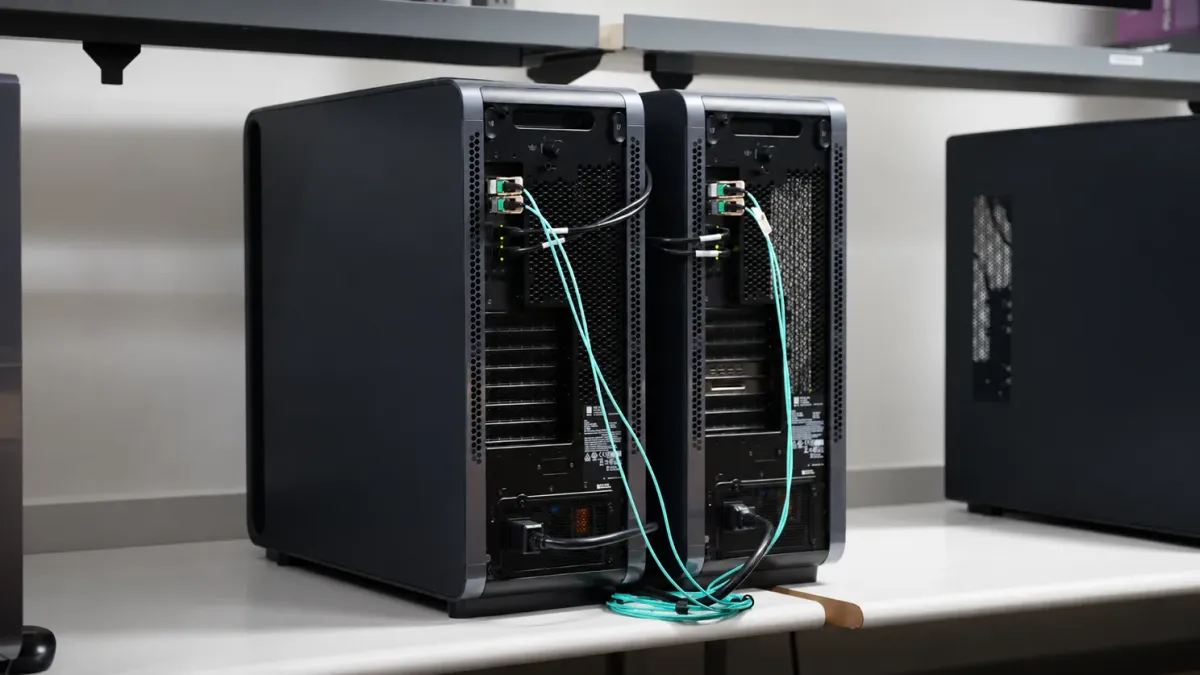
- Two DGX Stations linked over ConnectX-8 RDMA use tensor parallelism (TP=2), each holding about half the weights, behind one OpenAI-compatible endpoint; vLLM runs with multi-token prediction, FP8 KV cache and prefix caching.
- On the SPEED-Bench Coding dataset, total output throughput peaks at 607.8 tokens per second at concurrency 16, then drops to 385.0 at concurrency 32 with a mean request latency of 453.5 seconds.
Builder's takeThe useful number is that throughput falls at concurrency 32 with 453.5-second mean latency: running a frontier open model locally works, but only for small internal teams at low concurrency. If you want to self-host to keep data in-house, measure the best concurrency on your own prompts the way this post does, then compare per-token cost with on-demand cloud calls.
// Background · from #Open models
Full timeline →- Nov 14 llama.cpp and ggml reach v1.0.0: breaking changes to the public C API will now bump the major version
- Nov 13 IBM releases the LLMON markup language with Granite 4.1 3B and 8B preview models: reserved special tokens separate instructions from data, blocking 47% more injection attacks on OPI than the best frontier model tested
- Nov 13 DeepSeek V4-Pro, V4-Flash and V4.1-Flash arrive on SageMaker JumpStart: MIT-licensed MoE models with a 1M-token context