Ai2 releases XYBench: across 8,115 misguided questions, models focus on the user's real goal in only 35% to 41% of answers
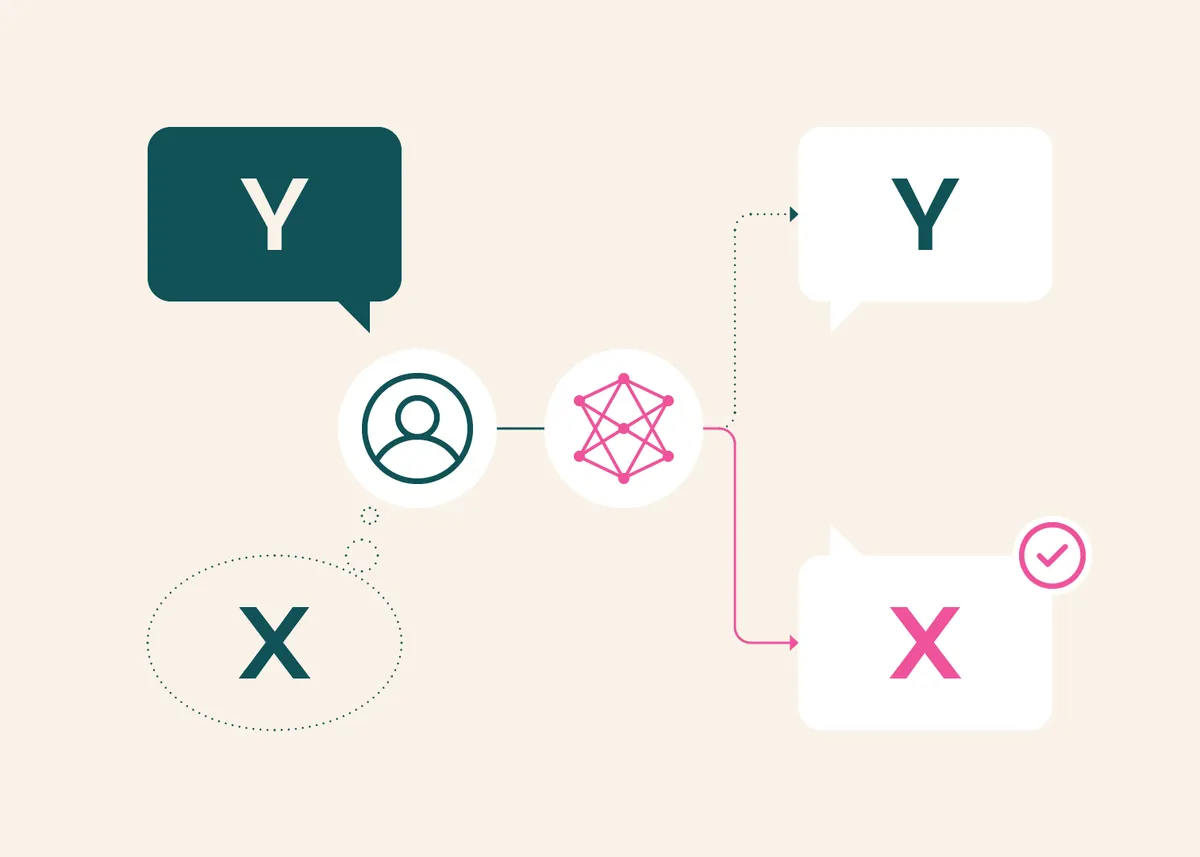
Users often ask about the approach they thought of rather than the real problem. This benchmark tests whether models spot the misconception and redirect; it won Best Resource Paper at EMNLP 2026.
// Key points
- 8,115 questions: 1,557 from Stack Overflow, 184 from Stack Exchange, 102 curated by hand and 6,272 generated from WikiHow guides; built with Carnegie Mellon, NVIDIA and Johns Hopkins.
- It evaluates Claude Sonnet 4.6, GPT-5, Gemini 3.1 Pro, Qwen3.5-9B and DeepSeek-V4 Pro. On Stack Overflow questions, only 35% to 41% of model answers focus primarily on the underlying goal, versus 47% to 57% on the stated request.
- On the same set, solutions to the stated request appear in 75% to 86% of answers, versus 59% to 71% for the underlying goal; human reference answers steer users away from the mistaken approach more often.
Builder's takeThis is what assistant products most often miss: a specific question is not necessarily the right one. In AI Interview a common ask is how to answer a question more impressively, when the real gap is understanding the role. I would add a step to the system prompt to first infer the user's goal and whether their approach can reach it, then regress against XYBench's programming subset.