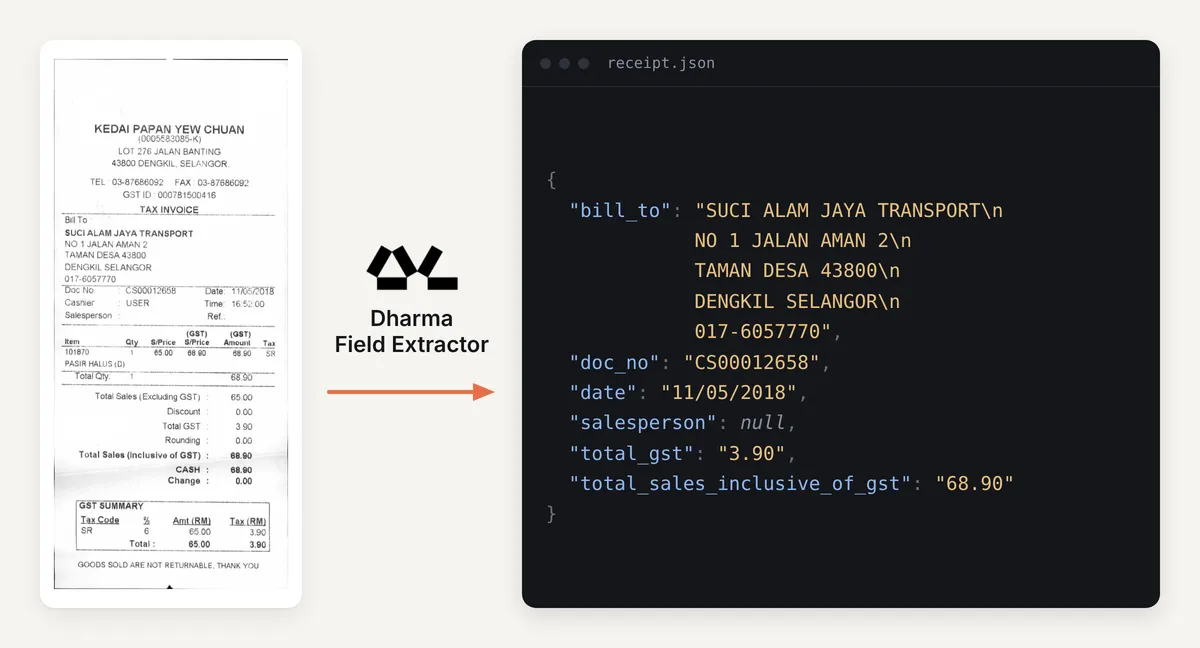
Dharma AI's 2B Field Extractor returns document fields as typed JSON, within 1.8 points of Claude Opus 5 on its benchmark at roughly 6 to 147 times lower cost
A small specialised model for a high-volume, well-defined job: pull specific fields out of invoices, forms and IDs into JSON your system can consume.
// Key points
- Built on DharmaOCR-LITE v1.1 (2B parameters) with a LoRA adapter trained on 43,384 examples; works open-ended or against an exact schema, returning null for fields not on the page
- The benchmark covers 546 documents across three request scenarios, 1,638 cases, scored by field-level F1 times value similarity times valid-JSON share
- The quality gap to general-purpose LLMs runs from 1.8 points (Claude Opus 5) to 9.3 points (GPT-5.6 Luna)
- Cost is roughly 6 times lower than GPT-5.6 Luna and 147 times lower than GPT-5.6 Sol, measured as self-hosted GPU time on one L40S at $2.24 an hour
Builder's takeNote the benchmark is the vendor's own and the frontier models still score higher, but the cost gap is large enough to matter. In the AI cloud drive, invoice and receipt field extraction is exactly this shape of job; I'd run a few hundred of our own documents through it and send only low-confidence ones to a large model.