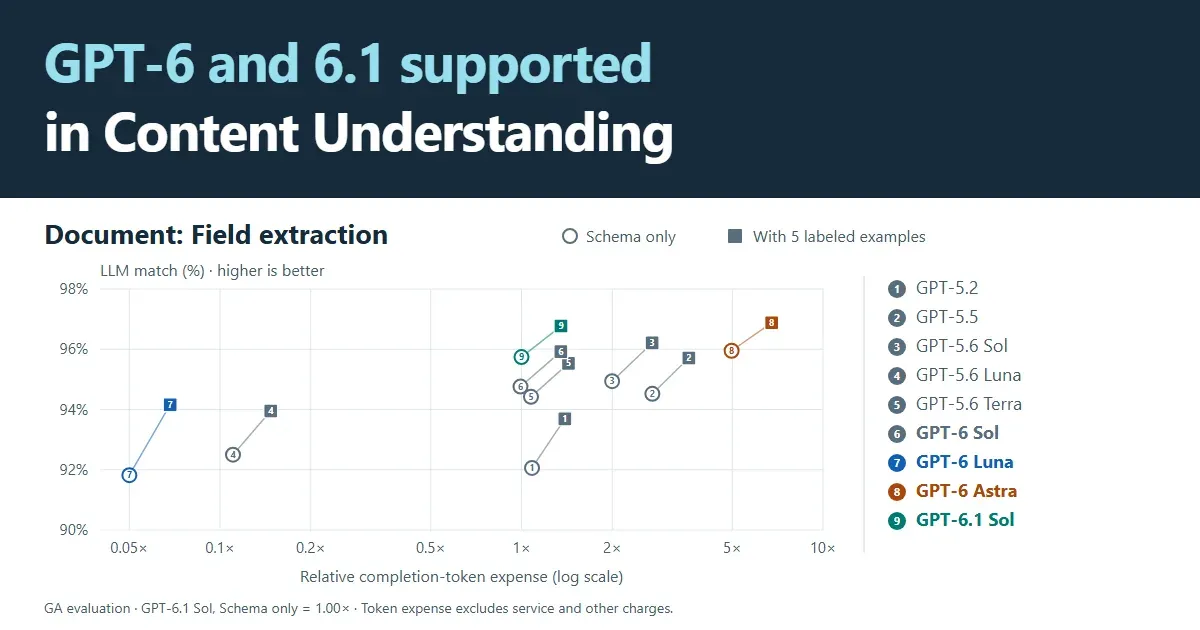
Azure Content Understanding adds GPT-6 and GPT-6.1 with published evals: GPT-6.1 Sol is the default for extraction, while GPT-6 Astra leads by 0.21 points at about 5x the completion-token spend
Microsoft updates its model recommendations for document, speech and video workloads, with the data behind them. The gaps between tiers, and the cheaper move of adding examples before upgrading.
// Key points
- Content Understanding adds the GPT-5.6, GPT-6 and GPT-6.1 families; for standard document extraction Microsoft suggests starting with GPT-6.1 Sol, and GPT-6 Luna when token cost matters most.
- In GA extraction, Astra leads Sol 95.95% to 95.74% with schema only, at about five times Sol's completion-token expense; in the Preview extraction evaluation Sol leads instead (96.06% vs 95.58%).
- Adding five labeled examples lifts Luna's extraction quality from 91.82% to 94.16%, with token expense still much lower than Sol's.
- The best model varies by task: Astra leads document segmentation (98.00% vs 97.10%), and GPT-6 Sol has the highest headline video Generation F1 (86.40%).
Builder's takeWhat this data shows is that the pricier tier often buys only a few tenths of a point. For field extraction in AI Cloud Drive, I would add five labeled examples to the cheap tier first and only then decide whether to upgrade, and evaluate and choose models separately for segmentation and extraction.