Best Practices for Full-Stack Product Development Under Tight Deadlines
ALT: Engineering team shipping full-stack product on tight deadline using AI architecture and agile best practices
Shipping Under Pressure: Best Practices for Full-Stack Product Development When Time Is the Constraint
Key Conclusion: Full-stack product development under tight deadlines demands more than speed — it requires disciplined prioritization, modular architecture, and deliberate communication patterns that keep quality intact while reducing waste. This list distills the practices that consistently separate teams who ship working software on schedule from those who accumulate technical debt, scope creep, and last-minute failures. Each item is drawn from the realities of end-to-end product engineering, not theoretical agility frameworks.
The practices below were selected based on patterns that emerge repeatedly in high-pressure product builds — the kind of projects where a founder needs a working product live, where a CTO is accountable to a board, and where "almost done" is not a business outcome. This is not a checklist for slowing down to be safe; it is a framework for going fast without breaking the things that matter most. Read through all items before committing to any single approach, because the most effective teams apply several of these in combination.
The Practices: How High-Performing Teams Deliver Full-Stack Products on Time
Ruthless Scope Definition Before the First Line of Code
Scope definition is the single highest-leverage activity in a time-constrained product build, and most teams underinvest in it. Ambiguous requirements are the primary cause of missed deadlines — not slow engineers, not inadequate tooling. When every stakeholder's mental model of the product differs slightly, those discrepancies compound into weeks of rework at the worst possible moment.
In work on compressed-timeline products, a pattern emerges consistently: teams that spend structured time upfront aligning on a Minimum Viable Product (MVP) — defined here as the smallest coherent set of features that delivers core user value — ship earlier and with fewer defects than teams that begin coding immediately. The discipline is not about being conservative; it is about being precise.
A practical approach is to write user stories at the feature level, assign each story a scope classification (in-scope for launch, post-launch, out of scope entirely), and require explicit sign-off from all decision-makers before development begins. Unresolved scope questions at kick-off always resurface as emergency rework mid-sprint.
- Best for: Founders, CTOs, and product leads who have stakeholders with competing priorities and a fixed launch date
- Watch out: Scope definition sessions can themselves become a delay if they lack a fixed time-box. Set a deadline for the definition process itself and hold it.
Architecture Decisions That Favor Speed Without Sacrificing Extensibility
Choosing the right architecture upfront is the difference between a product that ships and one that requires a full rewrite after the first user test. Under deadline pressure, there is a temptation to reach for the most familiar stack rather than the most appropriate one. Familiarity matters, but so does fit.
Monolithic architectures are often the correct choice for early-stage products under time constraints — they are faster to build, easier to debug, and simpler to deploy than microservices. The critical discipline is designing the monolith with clear internal module boundaries so that future decomposition into services does not require rewriting business logic. This is sometimes called a "modular monolith" pattern, and it is a mature, well-understood approach used by teams that prioritize shipping over architectural purity.
When AI capabilities are part of the product, the architecture decision carries additional weight. Integrating AI features as isolated, well-defined modules — rather than threading AI logic throughout the codebase — makes the product easier to test, easier to swap providers, and faster to debug when inference behavior changes. For teams thinking through how early-stage startups should approach AI system design on a lean budget, separating AI orchestration from core product logic is a consistent recommendation.
- Best for: Engineering leads who need to make architecture calls quickly with incomplete information
- Watch out: "We'll refactor later" is a statement that almost never resolves without dedicated time and owner accountability. If you introduce technical debt deliberately, document it explicitly and schedule the resolution sprint.
Vertical Slice Delivery Over Layer-by-Layer Development
Vertical slice delivery means building a small number of complete, end-to-end features — from database to UI — before expanding breadth. It is the opposite of the common anti-pattern where the database schema is "finished," then the API layer, then the frontend, only for integration problems to surface in the final days before launch.
The risk of layer-by-layer development under tight deadlines is catastrophic: integration failures discovered late have no budget of time left to fix. Vertical slices expose integration problems early, when there is still room to adapt. Each slice also produces a demo-able increment, which keeps stakeholders aligned and reduces the risk of building the wrong thing for weeks before anyone notices.
From a practical standpoint, this means the first sprint should result in a working, if incomplete, product that a real user could interact with. It will be rough. It will lack polish. But it will be real, and the feedback it generates is the most valuable input a team under deadline pressure can receive.
- Best for: Teams of three or more engineers working in parallel across frontend, backend, and infrastructure
- Watch out: Vertical slices require tight coordination between engineers. Without clear interface contracts defined upfront, parallel work creates merge conflicts and integration friction rather than speed.
Automated Testing Focused on Critical Paths, Not Coverage Metrics
Automated testing under deadline pressure is a subject of genuine tension. The common mistake is binary thinking: either skip tests entirely to move fast, or pursue comprehensive test coverage and miss the deadline. Neither extreme serves the product.
The correct approach is to identify the critical paths — the sequences of user actions that, if broken at launch, constitute a product failure — and write automated tests exclusively for those paths first. For a payments-enabled product, that means the checkout flow must be tested end-to-end before launch, regardless of how much else is tested. For an AI-powered product, it means the inference pipeline and its error states must be covered. Everything else is prioritized behind these.
This is not a license to skip testing broadly — it is a prioritization framework for when time is the binding constraint. As per established software engineering practice documented by organizations like IEEE, defects found post-deployment cost significantly more to resolve than those caught during development, which makes targeted automated testing one of the highest-ROI activities in a compressed build cycle.
- Best for: Engineering teams with at least one engineer who can set up CI/CD pipelines and write integration tests efficiently
- Watch out: Test suites that are slow to run will be skipped under pressure. Keep the critical-path test suite fast — if it takes more than a few minutes to run, engineers will stop running it locally.
Continuous Deployment From Day One, Not Day Ninety
Continuous deployment (CD) is the practice of automatically deploying every passing build to a live environment. Setting up CD infrastructure is often deferred as a "nice to have" until after launch. This is a costly mistake in deadline-constrained projects.
Without automated deployment, the last few days before a deadline are consumed by manual deployment work, environment mismatches, and configuration errors that do not appear until production. These are preventable problems. Setting up a basic CD pipeline — even a simple one that deploys to a single staging environment automatically — eliminates an entire category of late-stage failure.
The additional benefit is psychological: when deployment is routine and automated, the team's relationship with "going live" changes. Releases stop being anxiety-producing events and become ordinary operations. This matters enormously in deadline contexts because it removes the temptation to delay deployment out of fear, which is one of the more common last-mile failure modes.
- Best for: Any team with more than one developer shipping to a shared environment
- Watch out: CD pipelines require environment parity — staging and production must be configured identically. Environment drift is the primary reason CD pipelines fail to catch production issues during pre-launch testing.
Communication Protocols That Eliminate Ambiguity Without Creating Overhead
Communication failures are as responsible for missed deadlines as technical failures, and they are far less frequently discussed in engineering circles. In deadline-constrained builds, the communication anti-pattern that appears most often is an absence of decision logging: a call is made, everyone present understands it, and two weeks later half the team is operating on different assumptions because the decision was never written down.
The fix is lightweight but requires discipline: every significant decision — about scope, architecture, API contracts, third-party dependencies — gets written down in a shared, searchable location within 24 hours of the decision being made. This is not documentation for its own sake; it is insurance against the coordination failures that derail builds in their final stretch. According to industry practitioners, including guidance published on LinkedIn's engineering advice platform, breaking complex projects into clearly communicated sub-tasks with explicit owners is one of the most effective strategies for maintaining momentum under tight deadlines.
For teams working across time zones or asynchronously, this discipline is not optional — it is the foundation on which everything else depends. If you are also thinking about how to validate a product idea with real customers before building, clear documentation of validated assumptions plays a dual role: it accelerates development and de-risks the product direction simultaneously.
- Best for: Teams of any size, but especially distributed or asynchronous teams working across time zones
- Watch out: Documentation overhead can become a bottleneck if the format is too heavy. Use a lightweight standard — one paragraph per decision, capturing the decision itself, the rationale, and who made it. Nothing more is required.
Dependency Risk Mapping Before Commitments Are Made
Every full-stack product depends on external components: third-party APIs, cloud services, payment processors, authentication providers, AI inference endpoints. Each dependency is a potential point of failure that sits outside the team's direct control. Under deadline pressure, dependency failures — an API that is deprecated, a service that has an outage, a library that has a breaking change — are disproportionately damaging because there is no buffer time to absorb the impact.
Dependency risk mapping is the practice of explicitly cataloguing every external dependency before development begins, classifying each by its risk level (how likely is it to fail or change, and how badly would that affect the product?), and identifying a contingency plan for each high-risk dependency. For AI-powered products, this includes the AI provider's API stability, rate limits, and pricing model — all of which can change in ways that affect the product's viability.
As noted in guidance from product development practitioners at Encata, one of the most effective strategies for handling tough deadlines is proactively identifying dependencies that could block progress and sequencing development work to de-risk them early. The teams that handle deadline pressure most gracefully are those that encounter their hardest problems first, not last.
- Best for: Products that rely heavily on third-party infrastructure, APIs, or AI model providers
- Watch out: It is tempting to map risks and then not act on the findings. A risk map without contingency plans is a document that generates false confidence. For every high-risk dependency, specify the fallback before the dependency is integrated.
Instrumentation and Observability as First-Class Requirements
Observability — the ability to understand what a live system is doing through logs, metrics, and traces — is frequently treated as a post-launch concern. This is a mistake that compounds under deadline pressure. When a product launches and something goes wrong in the first 48 hours, teams without observability infrastructure spend hours in the dark reconstructing what happened from user reports. Teams with observability infrastructure diagnose and resolve the same issue in minutes.
The minimum viable observability setup for a deadline-constrained product launch includes: structured logging with enough context to reconstruct any request's lifecycle, error rate monitoring with alerting, and latency tracking for the critical user paths identified during testing. This is achievable in a single sprint and pays for itself the first time something breaks in production — which, for any product launching under time pressure, is a near-certainty rather than a possibility.
For products that include machine learning pipelines, observability requirements extend to model behavior monitoring. Teams building at the intersection of AI and full-stack engineering can find a practical framework for this in the discussion of how to build machine learning pipelines that scale past the prototype stage, where the transition from experimental to production-grade systems depends heavily on having the right monitoring in place.
- Best for: Any product going to production with real users, regardless of team size or timeline
- Watch out: Logging everything indiscriminately creates noise that makes observability less useful, not more. Start with the critical paths and instrument outward from there. Noisy logs that generate hundreds of alerts obscure the signal when something genuinely important breaks.
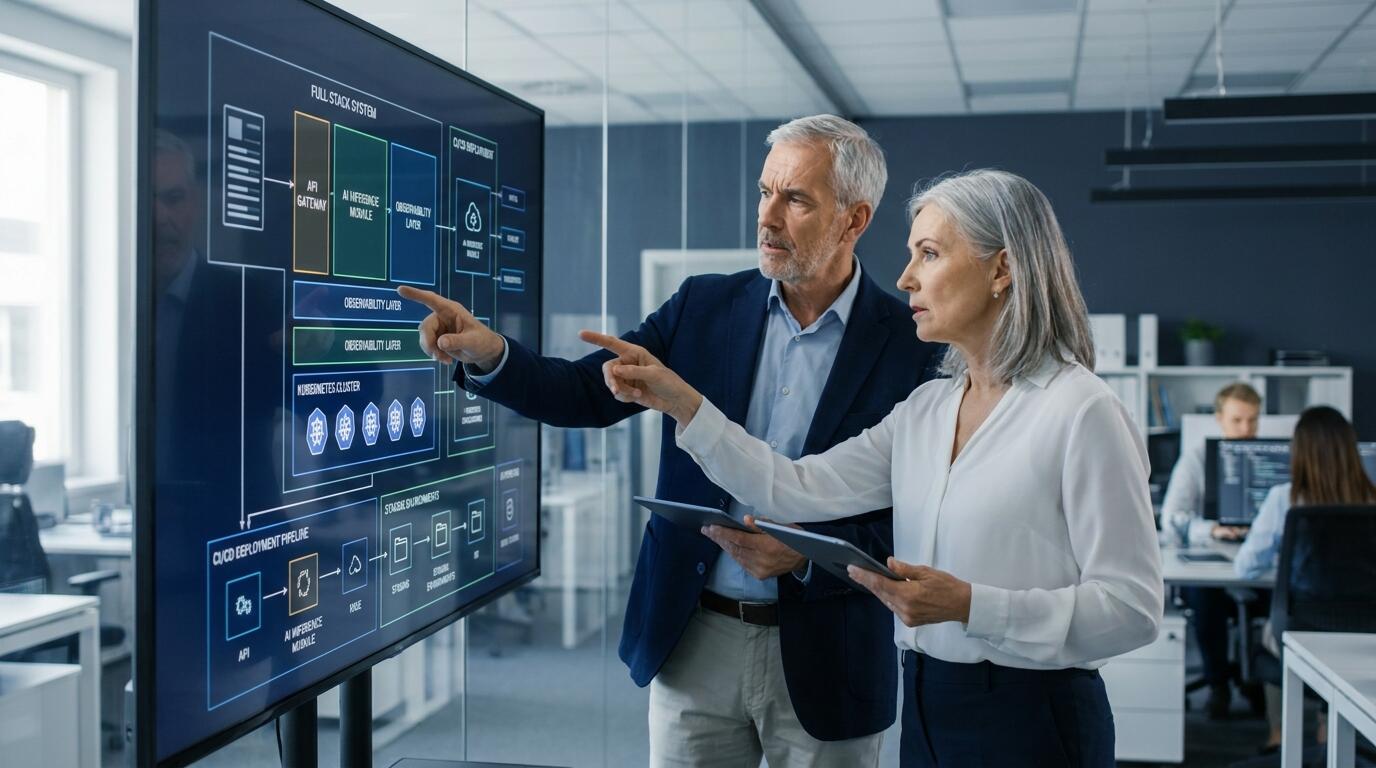
ALT: Engineering Director and AI Architect reviewing full-stack product deployment pipeline and system architecture under tight deadline constraints
Quick Comparison at a Glance
The following table summarizes each practice for teams that need a fast reference when evaluating where to invest limited time.
| Practice | Best For | Key Strength | Limitation |
|---|---|---|---|
| Ruthless Scope Definition | Any team with competing stakeholder priorities | Prevents rework at the most expensive moment | Can stall if stakeholders lack decision authority |
| Architecture Decisions for Speed + Extensibility | Engineering leads making early-stage technical calls | Reduces rewrite risk while maintaining launch velocity | Requires upfront architectural judgment not all teams have |
| Vertical Slice Delivery | Multi-engineer teams with parallel workstreams | Surfaces integration failures early, keeps stakeholders aligned | Requires tight coordination and upfront interface contracts |
| Automated Testing on Critical Paths | Teams with CI/CD capability | High ROI on defect prevention per hour invested | Requires knowing which paths are truly critical |
| Continuous Deployment From Day One | Any team with shared environments | Eliminates an entire class of late-stage deployment failures | Requires environment parity to be effective |
| Communication Protocols | Distributed or asynchronous teams especially | Prevents decision drift that derails builds mid-flight | Only works if the team maintains the discipline consistently |
| Dependency Risk Mapping | Products relying on third-party APIs or AI providers | Prevents late-stage blockers from external systems | Risk maps without contingency plans provide false confidence |
| Instrumentation and Observability | Any product with real production users | Reduces time-to-diagnosis when production issues occur | Poor logging standards create noise that reduces signal clarity |
How to Choose the Right Practices for Your Situation
Not every practice in this list warrants equal investment for every team in every context. Matching the practice to the situation is where judgment matters most.
If the primary risk is building the wrong thing — a common scenario when a founder is still learning the market — front-load scope definition and vertical slice delivery above all else. Getting working software in front of real users quickly is more valuable than perfect architecture or comprehensive testing in this context.
If the primary risk is a production failure after launch — more relevant when there are contractual obligations, regulated data, or paying customers from day one — prioritize observability, critical-path testing, and continuous deployment. These practices cluster around reliability rather than speed of initial delivery.
If the team is working across time zones or includes contractors who rotate — a pattern common in startup builds using external talent — the communication protocol practice becomes the load-bearing element. Everything else degrades without it.
A common misconception worth addressing directly: many teams believe that tight deadlines require choosing between speed and quality. This framing is false in its binary form. The practices above are not about slowing down to maintain quality — they are about eliminating the categories of waste (rework, late-stage integration failures, production outages, scope confusion) that cause teams to miss deadlines in the first place. The teams that ship fastest are almost always the teams that have the most discipline about what they choose not to build and not to break.
If you are a solo technical founder or a small team without a dedicated engineering director, the highest-leverage entry point is scope definition combined with vertical slice delivery and basic CD infrastructure. These three together address the most common failure modes without requiring a large team to implement.
Questions & Answers
Q1: How do you maintain code quality when shipping a full-stack product under extreme time pressure?
Code quality under deadline pressure is maintained through selective rigor rather than uniform rigor. Focus automated testing on critical user paths, enforce code review for any change that touches core business logic or data handling, and accept lower rigor elsewhere temporarily — but document the debt explicitly. Per software engineering best practices recognized by the IEEE, defects found late in development cost substantially more to fix than those caught early, which makes targeted quality investment genuinely speed-preserving rather than speed-reducing.
Q2: Is a microservices architecture appropriate for a product being built under a tight deadline?
A microservices architecture is generally not appropriate for deadline-constrained initial builds. Microservices introduce significant operational overhead — service discovery, distributed tracing, inter-service communication, independent deployment pipelines — that consumes build time without delivering user-facing value in early-stage products. A well-structured modular monolith is the more defensible choice for initial launches. It ships faster, is easier to debug, and can be decomposed into services later once the domain model is stable and the team has grown to justify the operational complexity.
Q3: How much time should a team invest in observability setup before a tight-deadline launch?
The investment in a minimum viable observability setup — structured logging, error rate monitoring, and latency tracking for critical paths — is typically achievable within a single sprint and is worth prioritizing even at the expense of lower-priority features. The cost of diagnosing a production failure without instrumentation is almost always higher than the cost of setting up basic observability before launch. For AI-powered products specifically, model output monitoring adds another layer that should be established before the first real users interact with the system.
Final Thoughts
Full-stack product development under tight deadlines is not a test of how fast a team can type. It is a test of how clearly a team can think under constraint — about what to build, what to defer, where to invest quality effort, and where to accept intentional imperfection.
Key Takeaways:
- Scope definition is the highest-leverage activity in any compressed build, and most teams underinvest in it relative to its impact on delivery outcomes.
- Architecture choices made under deadline pressure carry compounding consequences — a modular, deployment-friendly structure pays for itself multiple times over.
- Vertical slice delivery and early CI/CD setup together eliminate the most common last-mile failure modes that cause deadline misses.
- Automated testing focused on critical paths delivers meaningfully higher ROI per engineering hour than broad coverage metrics under time constraints.
- Observability is not optional for any product with real users, regardless of timeline — production failures will occur, and the cost of diagnosing them without instrumentation is always higher than the cost of setting up basic monitoring before launch.
The next step for any team evaluating these practices is to identify which two or three apply most directly to their current highest-risk areas — and address those first, before writing another line of feature code.
Ready to ship something real? Explore the work, projects, and expertise at the Darius website — and see how end-to-end product thinking, from AI architecture to full-stack execution, can accelerate your next build. Whether you are an early-stage founder or a scaling team, reach out and start the conversation about what it takes to go from idea to live product.
References & Further Reading
- Navanath Jadhav. "Don't Get Stressed, Organize: Mastering Tight Deadlines in Software Development".
https://navanathjadhav.medium.com/dont-get-stressed-organize-mastering-tight-deadlines-in-software-development-6fa443b644ed - LinkedIn Collective. "You Have a Complex Project with a Tight Deadline: What Are Some Strategies?".
https://www.linkedin.com/advice/1/you-have-complex-project-tight-deadline-what-some-i0taf - Encata. "How to Handle Tough Deadlines in New Product Development".
https://www.encata.net/blog/how-to-handle-tough-deadlines-in-new-product-development - IEEE. Software Engineering Body of Knowledge and Standards on Software Quality and Testing.
https://www.ieee.org/
Note: Standards and industry guidance may be updated; please check the latest official documents or consult professional advisors for the most current recommendations.