A Founder's Guide to Evaluating New Model Releases This Quarter
ALT: Founder evaluating new AI model releases on a laptop, comparing benchmarks and product fit this quarter
What You'll Gain: A Practical Framework for Evaluating AI Model Releases
Key Conclusion: Evaluating new AI model releases requires more than reading benchmark leaderboards. This guide gives founders and engineering leads a structured, cost-conscious process for assessing whether a newly released model deserves integration into a production AI product — covering capability mapping, cost-per-token analysis, latency profiling, reliability signals, and vendor risk assessment. By following this framework, you will move from reactive hype to deliberate, defensible model selection decisions.
Every quarter, a cluster of new model releases lands on the community's radar simultaneously. Some come with detailed technical reports; others arrive with marketing positioning that outpaces the actual capability. For founders building AI products, this creates a real operational problem: you cannot evaluate everything, but you cannot ignore the field either. A model you overlook might undercut your cost structure or unlock a capability your users need. A model you adopt too quickly might introduce regressions your users feel before you do.
This guide is written for engineering-minded founders, technical leads, and product builders who need a repeatable process — not a one-time scramble — for working through new model releases without losing weeks of velocity.
Before You Start: Prerequisites and Preparation
Evaluating a new model release is an engineering task dressed in a product decision. Before you open a model card or run your first API call, you need to know what you are actually measuring against.
Define your current baseline clearly. "The model we use today" is not a baseline. A usable baseline is a set of representative inputs from your production distribution, a scoring rubric your team has agreed on, a latency budget that reflects your product's SLA, and a cost figure you are actively trying to beat or justify. Without this, every new model evaluation becomes impressionistic — you end up with "it felt better" rather than "it scored higher on our rubric with 18% lower token cost."
Understand your product's model dependency surface. Some products touch a single model in a single call. Many production AI products touch multiple models across retrieval, classification, generation, and post-processing steps. Know which layer you are evaluating a new release for before you begin. Swapping a generation model affects different things than swapping a re-ranker or an embedding model.
Estimate your evaluation budget honestly. API calls during evaluation cost money. So does engineering time. A rigorous evaluation of a new flagship model against a realistic production sample can take significant API spend depending on your volume. Factor this in before you commit. The cost of a hasty evaluation that leads to a bad production swap is higher, but the cost of over-engineering an evaluation process for a marginal use case is also real.
Gather your evaluation dataset in advance. This is the step teams most often skip. A representative slice of your production inputs — ideally labeled with expected outputs or human judgments — should already exist before any model release happens. If you are building one from scratch each time, you are starting from zero on every evaluation cycle, which compounds the time cost.
Checklist before starting:
- A documented baseline: current model, current cost-per-unit, current latency p50/p95, current output quality score on your internal rubric
- A representative evaluation dataset drawn from real production inputs, not synthetic edge cases
- A scoring rubric your team can apply consistently, even if it is simple
- An API key and budget allocation for the new model
- A clear statement of which product layer this model would replace or augment
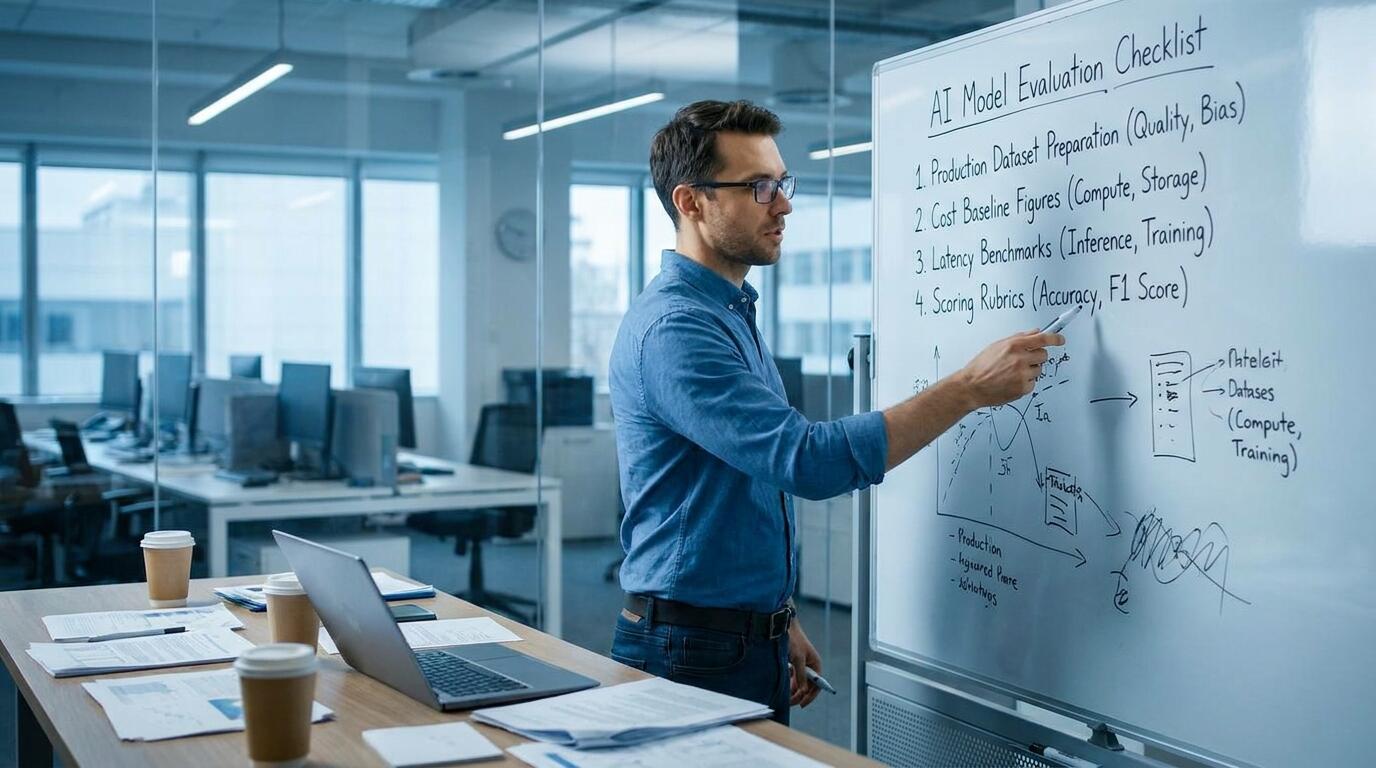
ALT: Engineer preparing AI model evaluation checklist with production dataset and cost baseline on whiteboard, quarterly review process
Step-by-Step: How to Evaluate a New Model Release for Production Use
Step 1: Read the Technical Report Before the Marketing Page
The first thing to do when a new model drops is locate its technical report, model card, or system card — not the blog post. The blog post is written to generate excitement. The technical report is written to document behavior, and it contains signals that matter for production: training data cutoffs, known failure modes, safety mitigations that may affect output format, and benchmark conditions that may or may not reflect your use case.
Pay specific attention to benchmark methodology. Many reported scores on reasoning or coding benchmarks are measured under conditions — chain-of-thought prompting, specific temperature settings, multi-shot examples — that you may not replicate in your production prompt. A model that scores highly on a benchmark under ideal conditions may underperform relative to that score in your actual call pattern.
Tip: Look for contamination disclosures. Some technical reports acknowledge that evaluation benchmarks may have appeared in training data. This does not automatically invalidate the scores, but it should calibrate your confidence in them.
Step 2: Map the Model's Stated Capabilities to Your Actual Requirements
New model releases are often positioned around headline capabilities: longer context windows, better reasoning, improved instruction following, multimodal input. Before running any evaluation, write down which of these capabilities are relevant to your product and which are irrelevant.
This sounds obvious, but in practice, teams often spend evaluation cycles on capabilities they will never use in production. If your product is a structured data extraction pipeline, a model's improvement in long-form creative writing does not move the needle. If your product relies on consistent JSON output, a model's score on mathematical reasoning benchmarks tells you almost nothing.
The pattern we consistently see in production AI products is that the most impactful model improvements are often in areas that do not make headlines: better instruction adherence on edge-case inputs, lower hallucination rate on domain-specific queries, or improved consistency across paraphrased versions of the same prompt. Look for evidence of these in the technical report and in early community evaluations before you invest in your own testing.
Tip: Build a two-column mapping table: "Capability the model claims" versus "Capability my product needs." If the overlap is thin, the evaluation priority is low regardless of the model's overall benchmark position.
Step 3: Run a Structured Evaluation Against Your Baseline Dataset
This is where evaluation becomes empirical rather than impressionistic. Take your representative production dataset and run it through both your current model and the new release, using identical prompts and call parameters where possible.
Score the outputs using your pre-agreed rubric. If your rubric involves human judgment, do a blinded evaluation where the scorer does not know which output came from which model. Confirmation bias in model evaluation is real and consequential — teams consistently rate outputs from the model they already prefer more favorably when they know the source.
Track the following dimensions per output:
- Accuracy or correctness relative to your expected output
- Format compliance (does it follow the output schema you specified)
- Consistency across paraphrased or lightly varied inputs
- Refusal rate on legitimate requests (over-safety is a production issue, not just a theoretical one)
Aggregate your scores before drawing any conclusions. A model that wins on 60% of samples but catastrophically fails on 10% of samples may be worse for production than a model that is uniformly adequate across all samples, depending on the failure cost in your product.
Tip: Run the evaluation twice with different random seeds or temperature settings if your call pattern involves non-zero temperature. Model behavior variance is itself a signal.
Step 4: Profile Latency and Throughput Under Realistic Load
Benchmark scores say nothing about latency. A model that produces better outputs but adds meaningful latency to your critical path may degrade user experience in ways that outweigh the quality improvement — or it may be perfectly acceptable if your product is asynchronous. You need to measure this rather than assume it.
Run latency tests against the new model's API using inputs that match your production length distribution. Measure time-to-first-token (important for streaming interfaces) and total generation time separately. Check the provider's rate limits and whether they match your expected peak throughput needs.
Latency can vary significantly by provider, region, and time of day. A single latency test is a data point; a distribution across multiple times of day is a signal you can act on.
Tip: If the new model is available through multiple providers or deployment options, test latency across at least two. Routing flexibility is a hedge against provider-specific degradation.
Step 5: Calculate Total Cost of Ownership, Not Just Token Price
Input and output token prices are the most visible cost dimensions, but they are not the whole picture. When evaluating a new model's economics, account for:
- Token price differential relative to your current model
- Changes in output verbosity (a model that generates longer outputs for equivalent tasks increases cost even at the same per-token rate)
- Prompt engineering costs: does the new model require a longer or more complex system prompt to achieve comparable behavior
- Evaluation and migration engineering time (a real cost that is often excluded from ROI calculations)
- Potential changes to your downstream processing if the new model's output format differs from your current model's
The goal is not to find the cheapest model; it is to find the model that delivers the best outcome per dollar spent across your full production stack. A model that is 20% cheaper per token but requires 30% more tokens to produce the same quality output is not a cost improvement.
For a deeper perspective on when to build your own infrastructure versus relying on third-party model APIs, the analysis in Build vs. Buy for AI Infrastructure: Revisiting the Framework for Late 2026 is directly applicable to the economics of model selection decisions.
Tip: Build a simple cost model spreadsheet before the evaluation. Fill in the numbers as you gather them. This forces clarity and makes the final decision defensible to stakeholders who were not in the evaluation process.
Step 6: Assess Provider Reliability and Vendor Risk
A model's quality is irrelevant if the provider's API is unreliable in production. Before committing to a new model release, assess:
- Uptime history of the provider (check community reports and status pages, not just the provider's own SLA statements)
- Rate limit structure and whether it fits your peak traffic profile
- Provider's track record on model deprecation timelines — how much notice do they give before removing a model version
- Whether the model is available through more than one inference provider, which gives you a fallback
Vendor concentration risk is a real concern for production AI products. A model that is only available through a single provider with a history of capacity constraints creates a single point of failure that no amount of output quality improvement can compensate for.
Tip: Check whether the provider offers a model version pinning mechanism. Being able to pin to a specific model version prevents unexpected behavior changes from silent model updates — something that has caused production incidents across many AI products.
Step 7: Make a Scoped, Reversible Adoption Decision
The output of a model evaluation should not be a binary "adopt" or "reject" decision. It should be a scoped recommendation: adopt for which specific use case, at what traffic percentage, with what fallback, and with what success metrics that will trigger full rollout or rollback.
If the new model shows a meaningful quality improvement on a specific task but has not been tested against your full production distribution, route a small percentage of that specific task's traffic to the new model and monitor the metrics you care about. Treat the initial deployment as an extended evaluation under real conditions.
The habit of making reversible, scoped adoption decisions is what separates teams that use model releases to improve their products from teams that generate evaluation reports that never make it to production.
For practical guidance on shipping changes at this cadence without accumulating technical debt, the framework in How to Ship Fast This Fall Without Sacrificing Product Quality covers the operational patterns that make incremental model rollouts sustainable.
Common Mistakes and Troubleshooting in Model Evaluation
| Symptom | Likely Cause | How to Fix |
|---|---|---|
| New model scores well in evaluation but underperforms in production | Evaluation dataset was not representative of real production inputs | Refresh your evaluation dataset from actual production traffic before each major evaluation cycle |
| Model adoption increases API costs unexpectedly after rollout | Output verbosity increased with the new model, offsetting the lower per-token price | Measure average output token count per task in evaluation, not just input tokens |
| Team cannot agree on whether the new model is better | No pre-agreed scoring rubric; judgment is subjective | Define and document the rubric before the evaluation begins, not after you have seen the outputs |
| Evaluation took weeks and the model was already superseded | No prioritization process for which releases to evaluate | Triage new releases against your capability mapping before committing engineering time |
| Production incident after model rollout caused by behavior change | Silent model update by provider without version pinning | Implement model version pinning and treat model version as a versioned dependency in your deployment |
| Latency regression after adopting a higher-quality model | Latency was not measured during evaluation or was measured under atypical conditions | Include latency profiling as a required step in every evaluation, not an afterthought |
Pro Tips for Better Model Evaluation Results
Build a standing evaluation harness, not a one-off script. The teams that evaluate new model releases most efficiently are the ones that have a reusable evaluation pipeline — a script that takes a model name, runs it against the baseline dataset, and outputs a structured comparison report. Building this once pays dividends across every subsequent evaluation cycle. The effort to build it is a one-time cost; the benefit compounds quarterly.
Use adversarial inputs alongside representative inputs. Your production dataset captures what your users do; adversarial inputs capture what they might do under edge conditions. A new model that handles your common cases well but breaks badly on edge cases can cause disproportionate support burden. Include a curated set of edge-case inputs in every evaluation.
Monitor the community evaluation landscape selectively. After a major model release, the community produces a large volume of informal evaluations, often within hours. Most of these are impressionistic or narrowly scoped. However, structured evaluations from teams with production use cases similar to yours are worth reading. The signal is in the specifics: what tasks, what prompts, what failure modes.
Separate the evaluation from the migration decision. A common mistake is conflating "this model is better" with "we should switch now." Even if a new model is demonstrably superior on your evaluation dimensions, the migration timeline should be driven by your team's capacity to manage it cleanly, not by the evaluation result alone. A good model adopted badly creates more problems than a slightly inferior model operated reliably.
Common misconception: Many founders assume that higher benchmark scores directly translate to better performance in their specific product. Benchmarks measure performance on standardized tasks under controlled conditions. Your product's tasks are neither standardized nor controlled. The benchmark is a prior; your evaluation is the evidence. Always prioritize your own evaluation results over published leaderboard positions.
The way the Darius briefing team approaches this — the agent pipeline behind the daily AI briefing runs model evaluation as a continuous process rather than an event — offers a practical illustration of how this can be operationalized at a sustainable cadence.
Common Questions
Q1: How do I decide which new model releases are worth evaluating at all?
Start with your capability gap, not the release announcement. If a new model claims improvement in an area that is not a bottleneck in your current product, it is low priority regardless of how much coverage it receives. Evaluate releases that claim improvements in the specific dimensions where your current model underperforms on your internal metrics. Triage takes less time than a full evaluation and prevents you from spending engineering cycles on models that would not change your product either way.
Q2: Is it necessary to evaluate every new model version from providers I already use?
Not necessarily. Point releases and minor version updates from established providers often involve targeted changes — safety tuning, specific capability improvements — that may not affect your use case. A reasonable heuristic is to run a lightweight regression check on minor versions (a sample of your hardest production inputs, not a full evaluation) and reserve full evaluation cycles for major releases or versions that the provider's documentation indicates contain significant capability changes.
Q3: How long should a thorough model evaluation take before committing to production use?
The time required scales with the scope of the adoption decision. A scoped evaluation for a single task type with a well-prepared dataset and existing evaluation tooling can be completed in a focused few days of engineering work. A full production-stack evaluation covering multiple task types, latency profiling, cost modeling, and reliability assessment will take longer — the exact duration depends on your product's complexity and dataset size. The instinct to shortcut this to capture a competitive advantage usually costs more time than it saves when the rollback happens. For guidance on evaluating AI development tools before committing, the same principles apply: define your criteria before you start, not after you have seen the options.
Summary
Evaluating new model releases is a repeatable engineering process, not a judgment call made under time pressure. Founders and technical leads who build this process explicitly — with standing datasets, clear rubrics, cost models, and scoped rollout patterns — make better model decisions and waste less engineering time on hype-driven evaluation cycles.
Key Takeaways:
- Read the technical report first; benchmark scores require context about methodology to be meaningful for your use case.
- Map claimed capabilities to your actual product requirements before investing evaluation time.
- Measure quality, latency, and cost together — optimizing for one dimension while ignoring the others produces incomplete decisions.
- Assess provider reliability and vendor risk as part of every evaluation, not as an afterthought.
- Make adoption decisions that are scoped and reversible; treat initial production deployment as an extended evaluation.
- Build evaluation tooling that is reusable; the investment compounds across every subsequent model release cycle.
The next step is concrete: identify the current model evaluation gap in your stack — the use case where you have the least visibility into whether a better option exists — and build your baseline dataset for that layer this week. Once the baseline exists, you are ready to evaluate the next release quickly and defensibly.
If you are building AI products and want a reliable signal on which model releases actually warrant your attention — with first-hand engineering context on what they mean for production systems — subscribe to Darius, a bilingual AI briefing written by an engineering director who runs AI products in production, with sourced, practitioner analysis on every item that matters.
References
- AI News Firm. "AI Model Release Timeline".
https://ai-news.helloworldfirm.com/models/ - Corporate Buyers' Guide to Enterprise Intelligence Applications. "Corporate Buyers' Guide to Enterprise Intelligence Applications".
https://39650877.fs1.hubspotusercontent-na1.net/hubfs/39650877/report_excerpt_-_corporate_buyer_s_guide_to_eia%20(1).pptx%20(1).pdf - Digital Event Horizon. "A Comprehensive Analysis of Building and Funding Models".
https://www.digitaleventhorizon.com/articles/A-Comprehensive-Analysis-of-Building-and-Funding-Models-Unveiling-the-Secrets-Behind-Successful-Startup-Ventures-deh.shtml - Institute of Electrical and Electronics Engineers (IEEE). IEEE Standards and Publications on Artificial Intelligence Systems.
https://www.ieee.org/
Note: Standards and model documentation may be updated; verify against the latest official releases or consult qualified technical advisors before making production decisions.